PagerSwarm
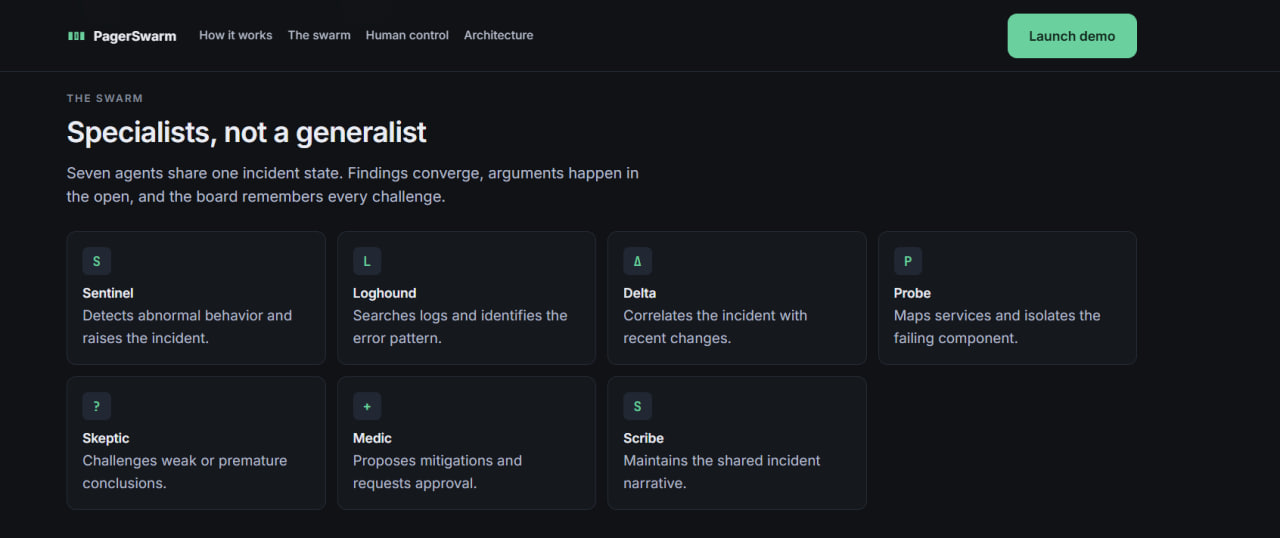
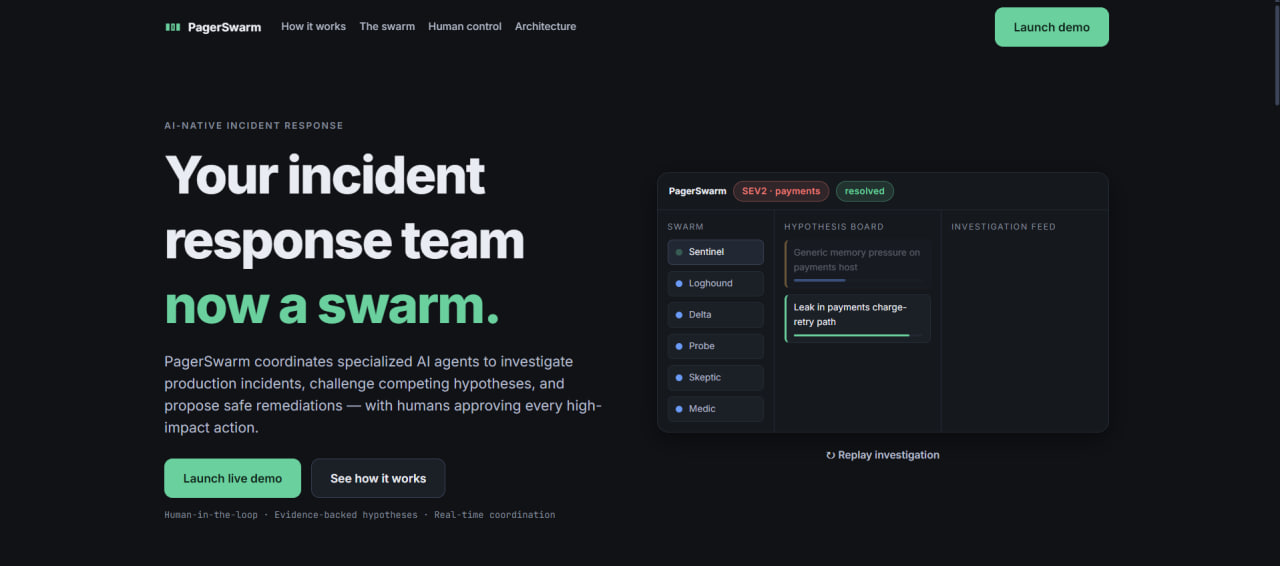
PagerSwarm runs a production break until a human signs off on the fix. Loghound, Delta, and Probe investigate together; Skeptic confirms a cause; Medic proposes a remedy and waits for approval before anything is applied.
What it does
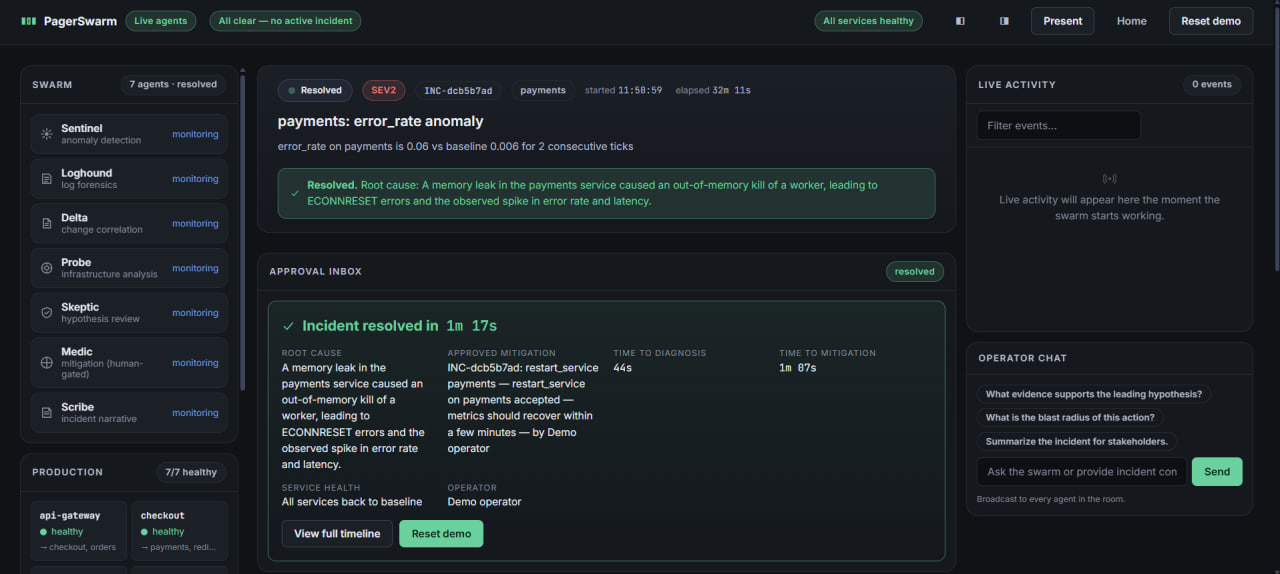
PagerSwarm is a live incident-response room for simulated production problems. When a service fails, AI agents investigate logs, changes, and service health, then agree on the likely cause. A human must approve any fix before it runs, and the system checks that the service recovers.
How the agents run concurrently
When Sentinel detects a service problem, it creates one shared incident and sends an event to the swarm. Loghound, Delta, and Probe start separate agent loops at the same time: Loghound checks logs, Delta checks recent deploys and changes, and Probe checks service links and metrics. They all read and write to the same Mozaik runtime state, which stores the incident, findings, possible causes, and timeline. As findings arrive, Skeptic runs independently to compare evidence, question weak ideas, and confirm a cause only when more than one source agrees. Medic then runs, selects the matching safe fix, and pauses for human approval. Scribe writes updates while the other agents are still working. The agents coordinate through shared events and state, not through a single step-by-step controller.